Demo
€030 days
Install the full stack on your server and try it on your real workloads. Then move to the licence without reinstalling.
Deploy the demoVentic is a product: you pay a monthly licence, per host or per company, on your own infrastructure. The licence doesn't depend on tokens; model consumption is prepaid credit you govern per group and per key.
Ventic is bought as a monthly software licence, per host or per company, at the same prices as Licman. Prices in EUR, VAT excluded, one-month commitment.
Install the full stack on your server and try it on your real workloads. Then move to the licence without reinstalling.
Deploy the demoOne licence per host running Ventic. Ideal to start with one or two servers.
Buy on LicmanAll of the company's hosts under one licence. Better value as the fleet grows.
Buy on LicmanInitial prices in EUR, VAT excluded, as of 28 October 2026. Changes apply to new requests; quotes and subscriptions already agreed keep their amount. Free 30-day demo. Looking for a managed service? It is sold separately on llm.netter.io.
| Criterion | Frontier subscription | Pay per token | Ventic On Premise |
|---|---|---|---|
| Predictable end-of-month cost | Flat fee | Depends on usage | Fixed licence; AI usage is separate prepaid credit |
| Spending control | Per account, little visibility | Provider dashboard | Group quotas, per-key limits, reservation before every request |
| Where the data goes | On the provider's servers | On the provider's servers | You decide per model: cloud or local runtime, optional PII |
| Choice of models | The provider's | Provider catalogue | DeepSeek, OpenRouter and your own runtimes, with stable aliases |
| Model stability over time | Changes without notice | Depends on the provider | Stable aliases; on local runtimes you govern the weights |
| Continuity during an outage | You stop with them | You stop with them | With several equivalent targets and failover routing |
| Audit and accounting | Not provided | Provider reports | Balanced ledger, activity log, export |
| Multiple companies and resale | No | No | Tenants, resellers and commissions |
| Infrastructure | Not needed | Not needed | Your own Kubernetes cluster; GPUs only for local models |
Sizing starts from the people and applications working together and the models you want to serve, not from tokens. Each VM of a managed deployment hosts one complete replica of the model.
Coding agents and apps keep their OpenAI or Anthropic SDKs. Changing model never touches the code.
Rules by team, request type, PII and budget: that is how 90% of traffic goes to open models.
Rent GPUs or bring up the local server with venticli apply. Autoscaling and off-hours shutdown included.
The agent connects outbound: no public IP, no VPN. The office server is a target like any other.
Reversibly masked PII and residency rules: requests with personal data stay local.
Budget reserved before every request. If a target is slow or down, the rule moves to the next one.
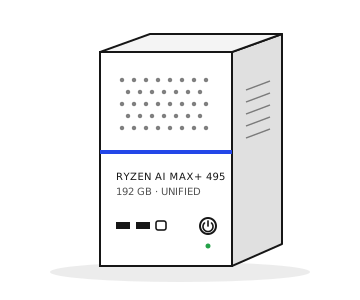
Ryzen AI Max+ 495 with 192 GB of unified memory: open models for a developer team, under the desk.
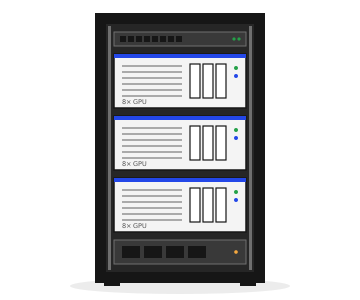
Multi-GPU nodes in your datacenter for the whole company: Ventic manages them as one compute pool, with autoscaling.
The best setups for your hardware, always up to date.
We give you inference configurations already optimised for your machines, so you get the most out of every GPU. For the latest open-weight models we fine-tune the serving parameters on the main inference engines: quantization, parallelism, batching, KV cache and context.
One fee for each distinct hardware configuration you want covered. The service is optional: Ventic works without it too.
Ryzen AI Max+ PRO 495, 192 GB. Ready for Ventic.
Manufacturer list price, VAT to be confirmed. About 6 developers per server; payback in 17 months vs the $100 plan.
Request the server from CompudOne hour to understand what you want to govern, which models you need and where they must run.