ALPHA
Medium/large enterprises · Agentic & vibe coding workloads

Introducing
Ventic.

A new declarative, intent-driven infrastructure that lets you deploy LLMs and regulate access to them. Create your own private LLM infrastructure with a provider-like feel, at a glance!

Access the alpha stage for free. Reach out to us at Show email or send me a direct message to request early access.

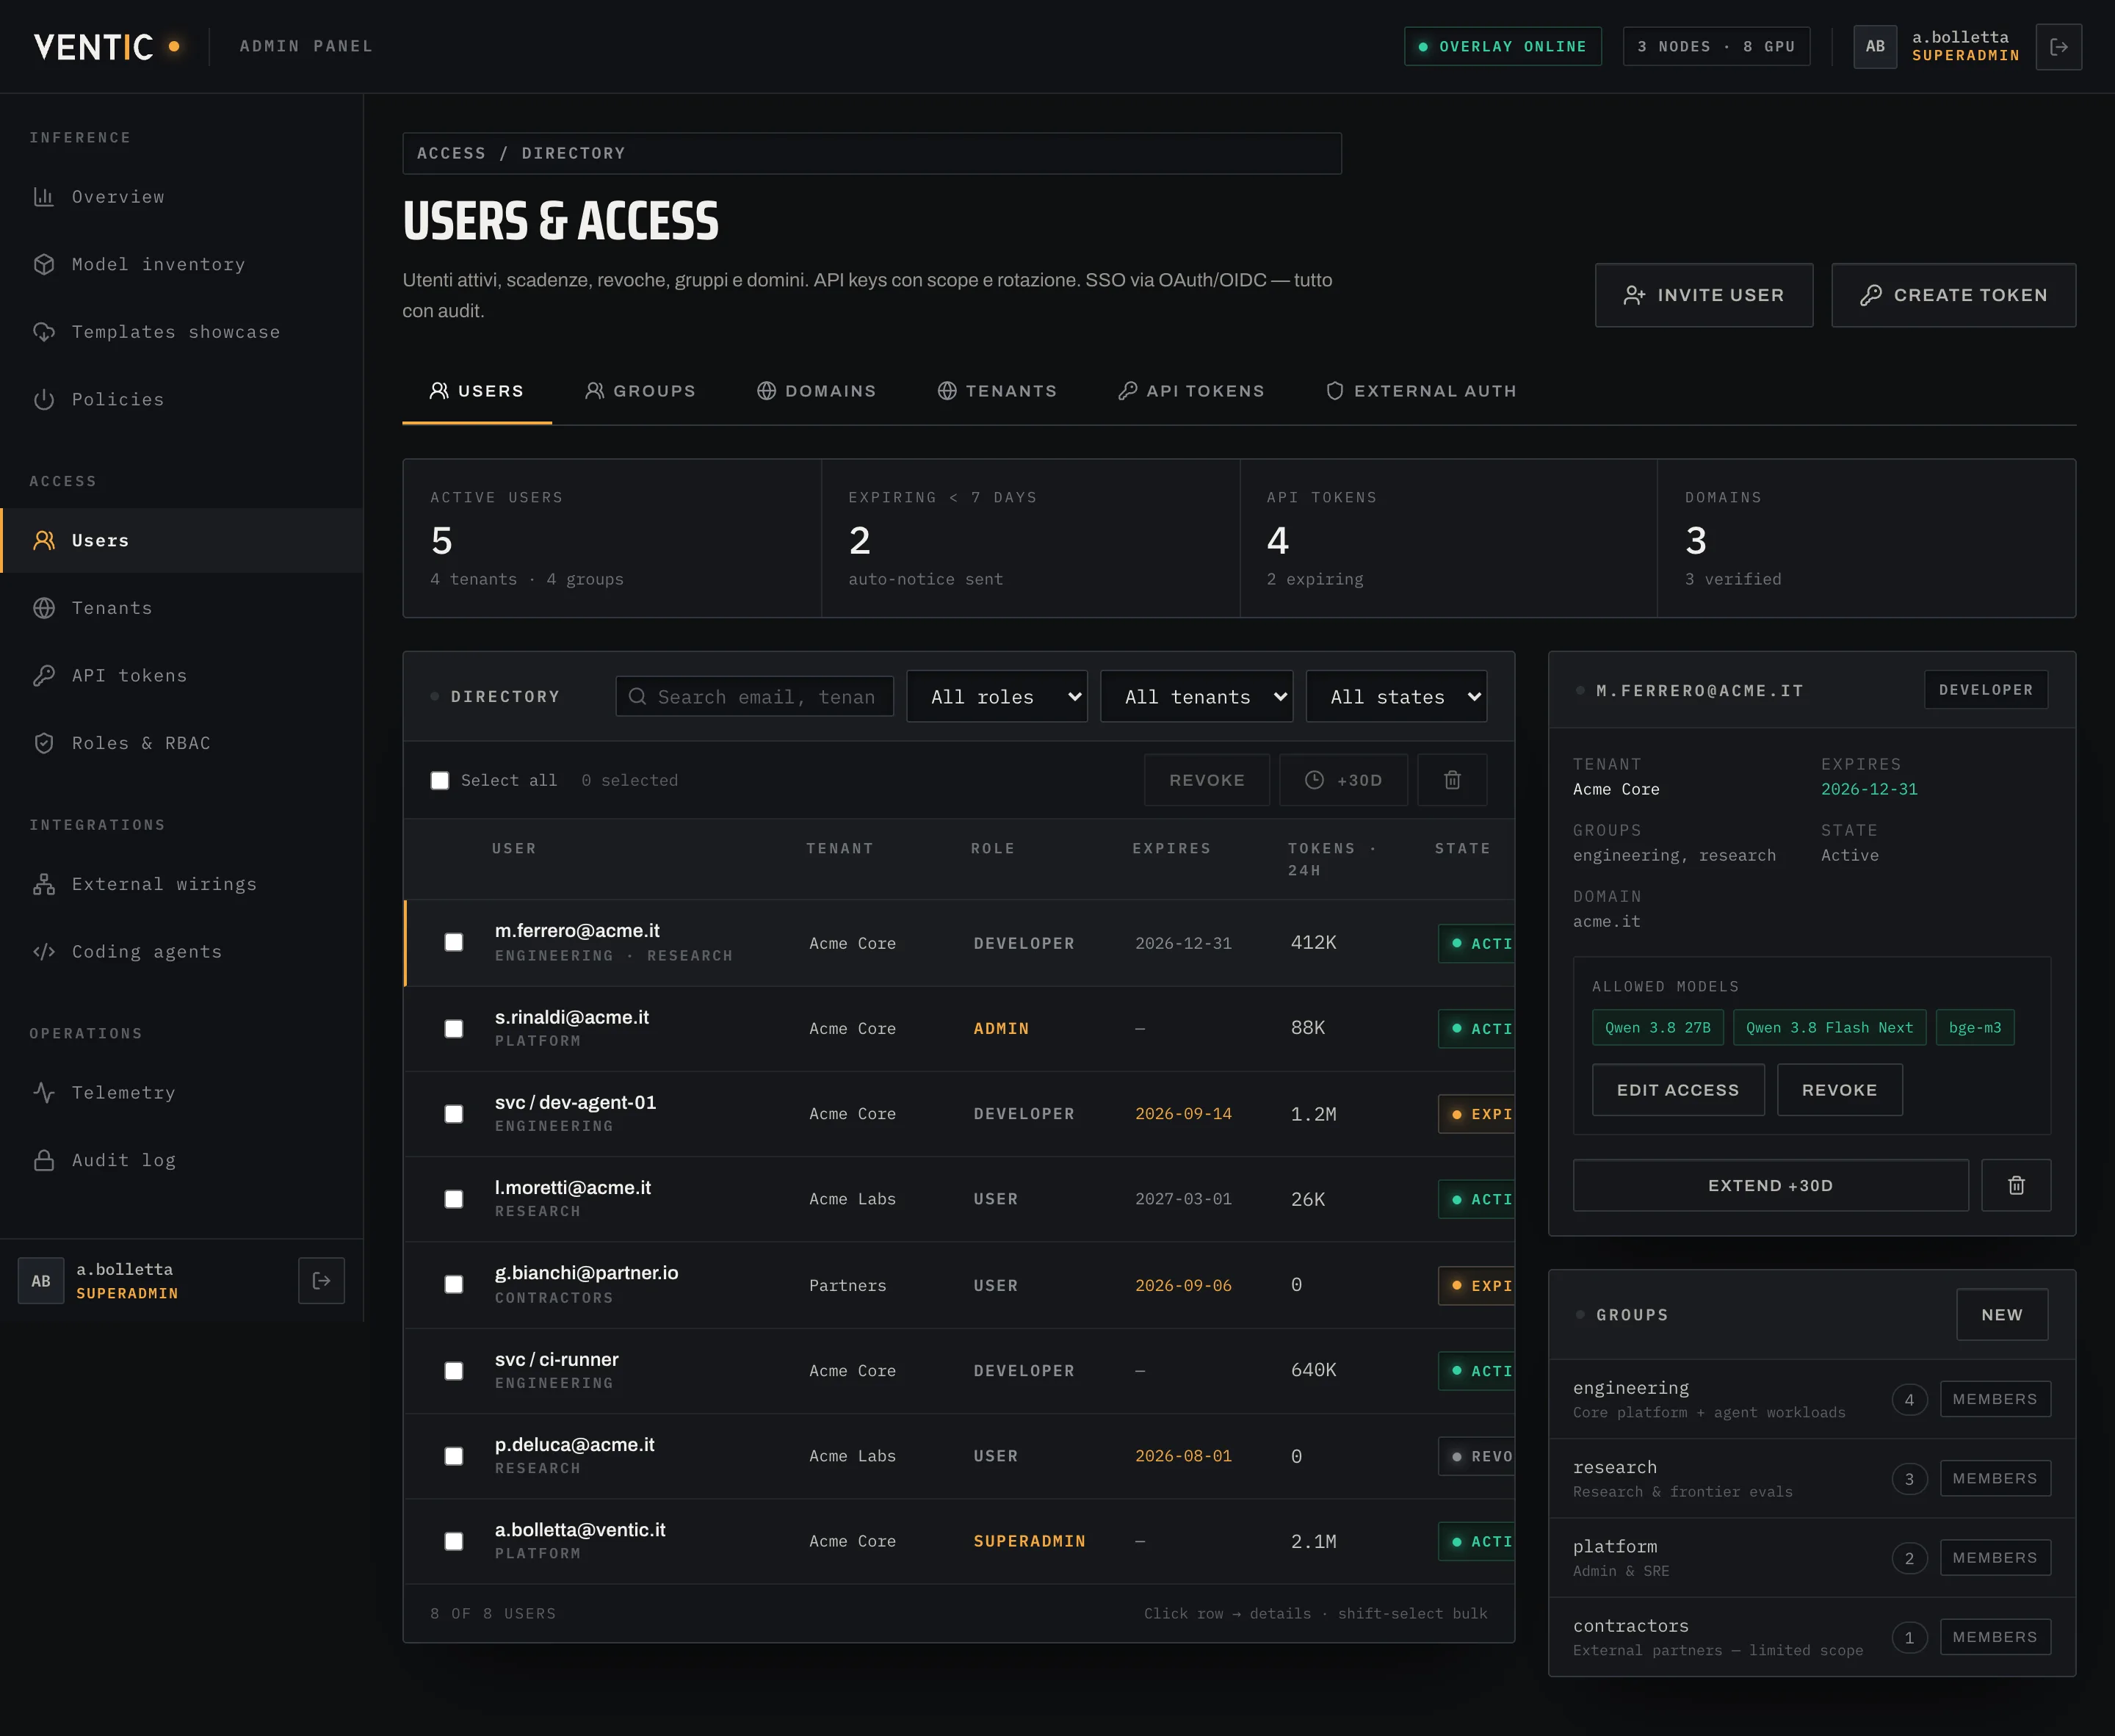
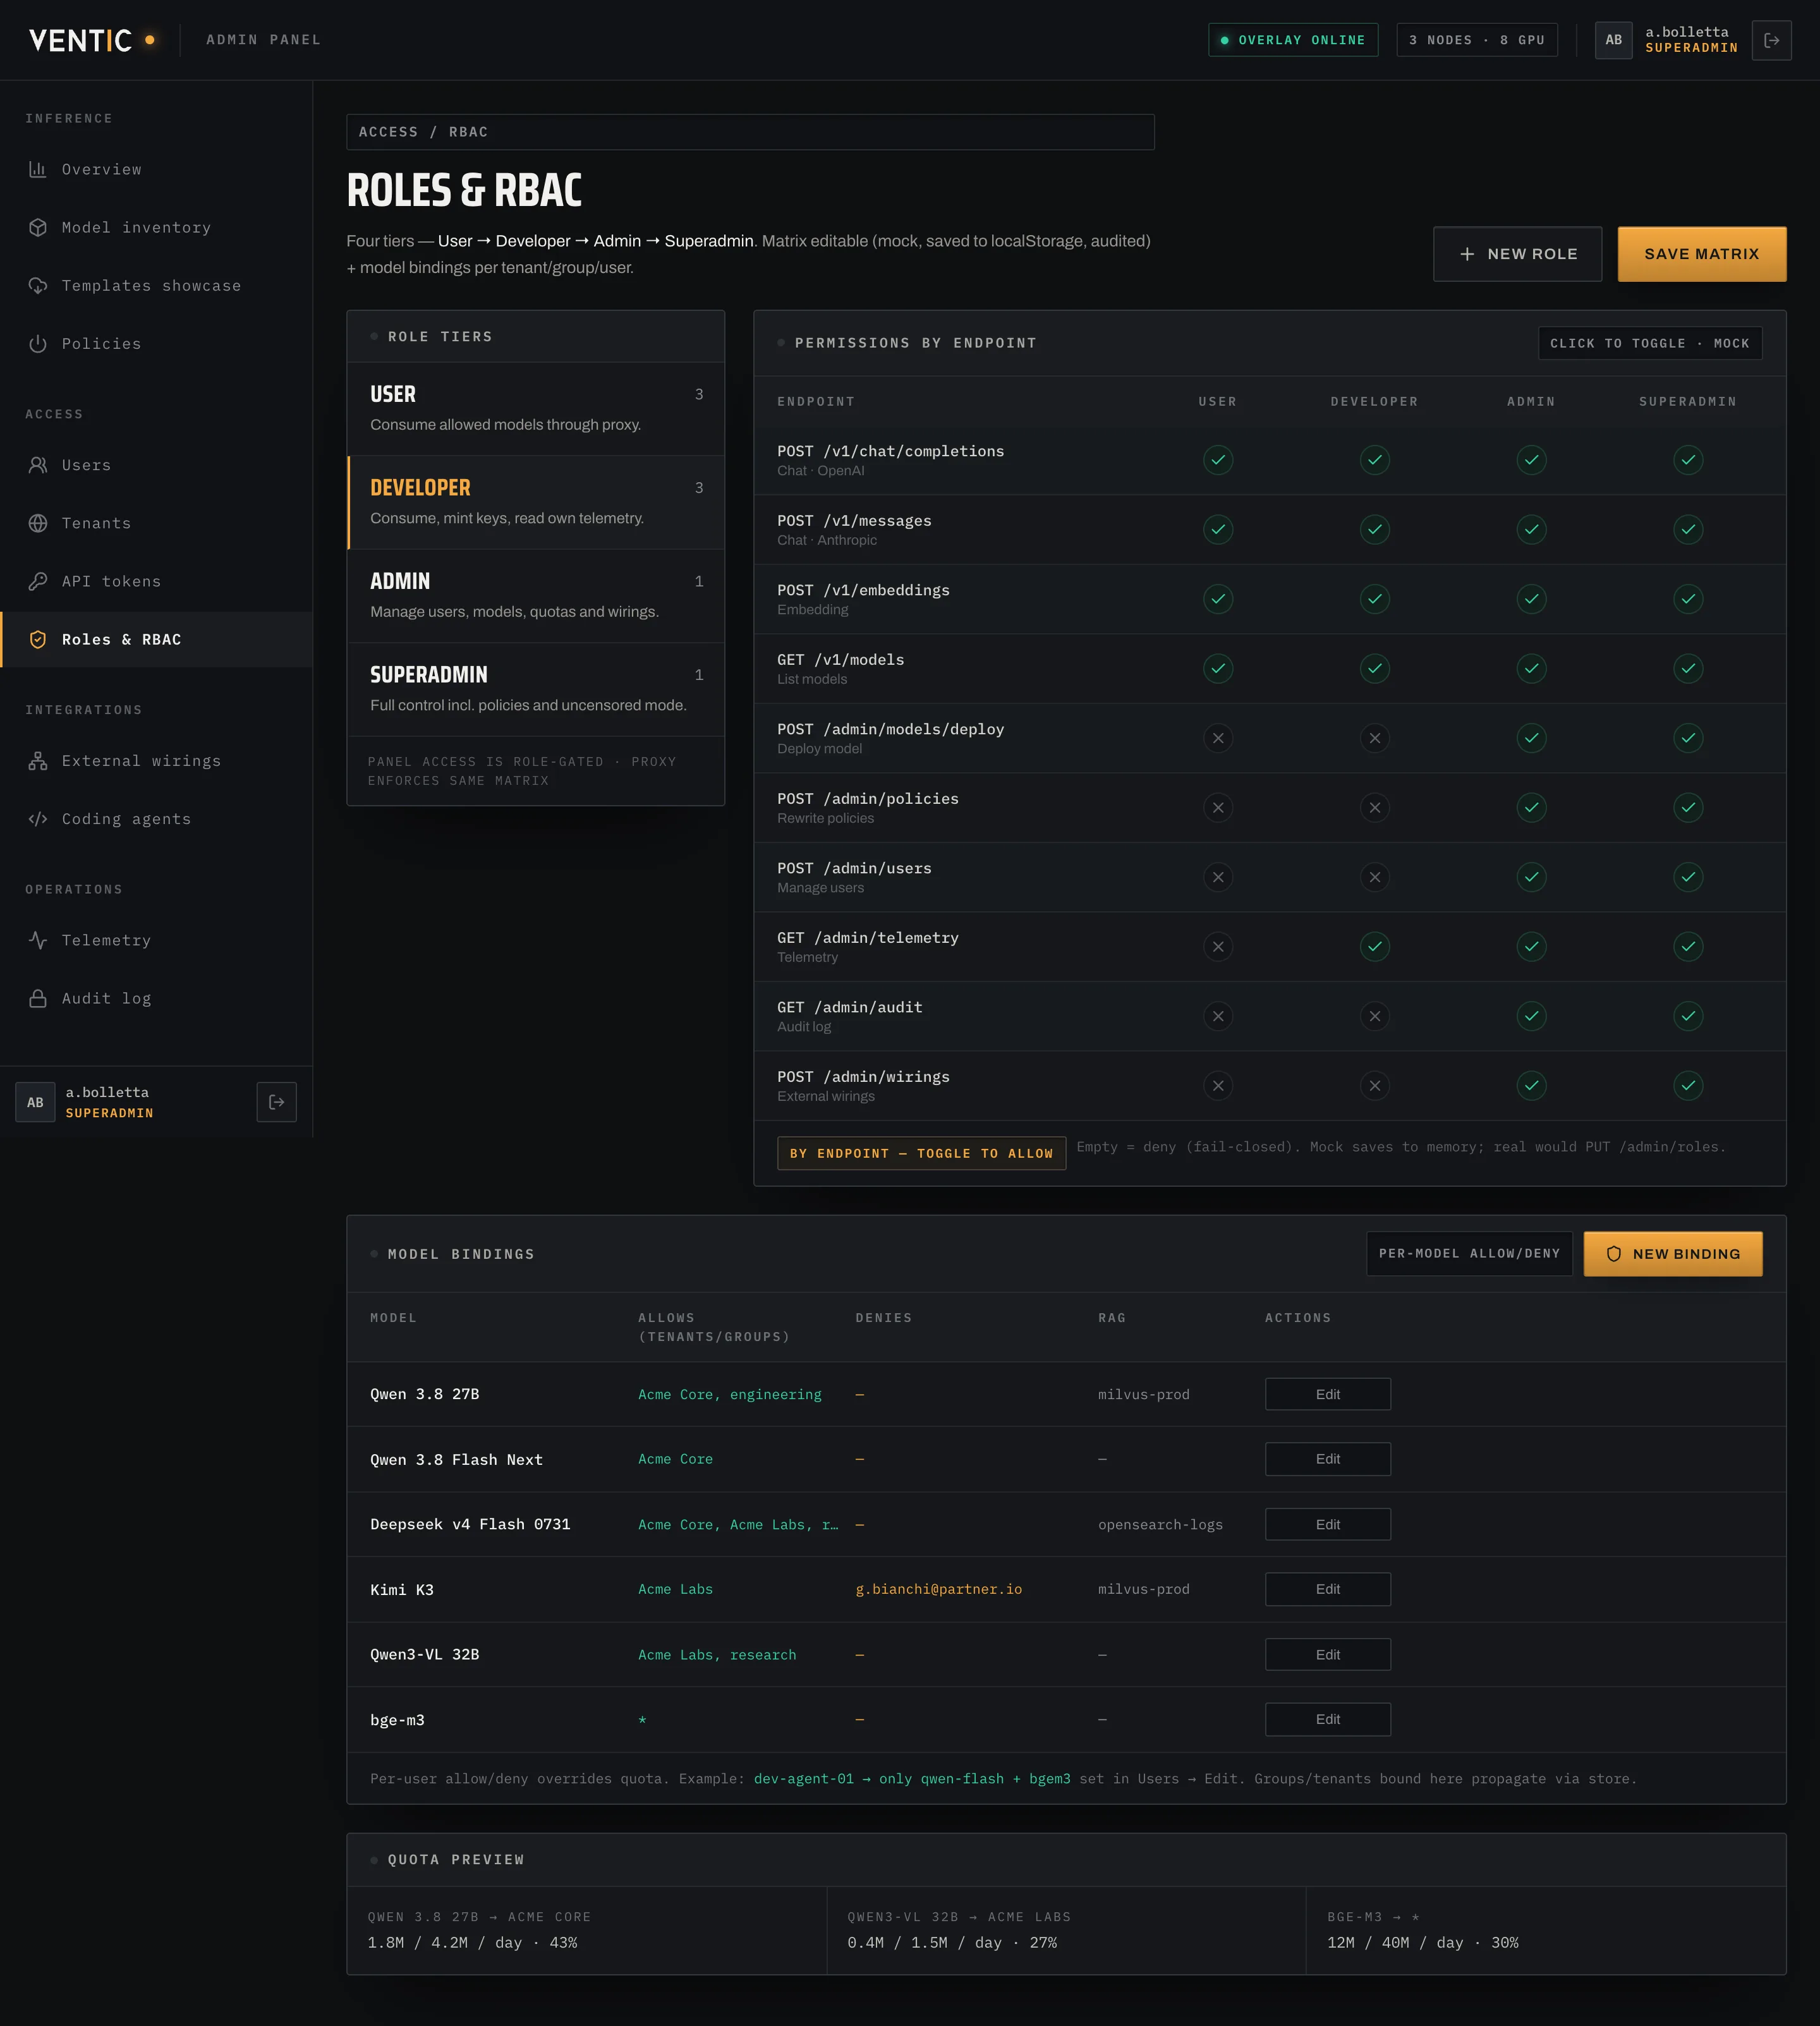
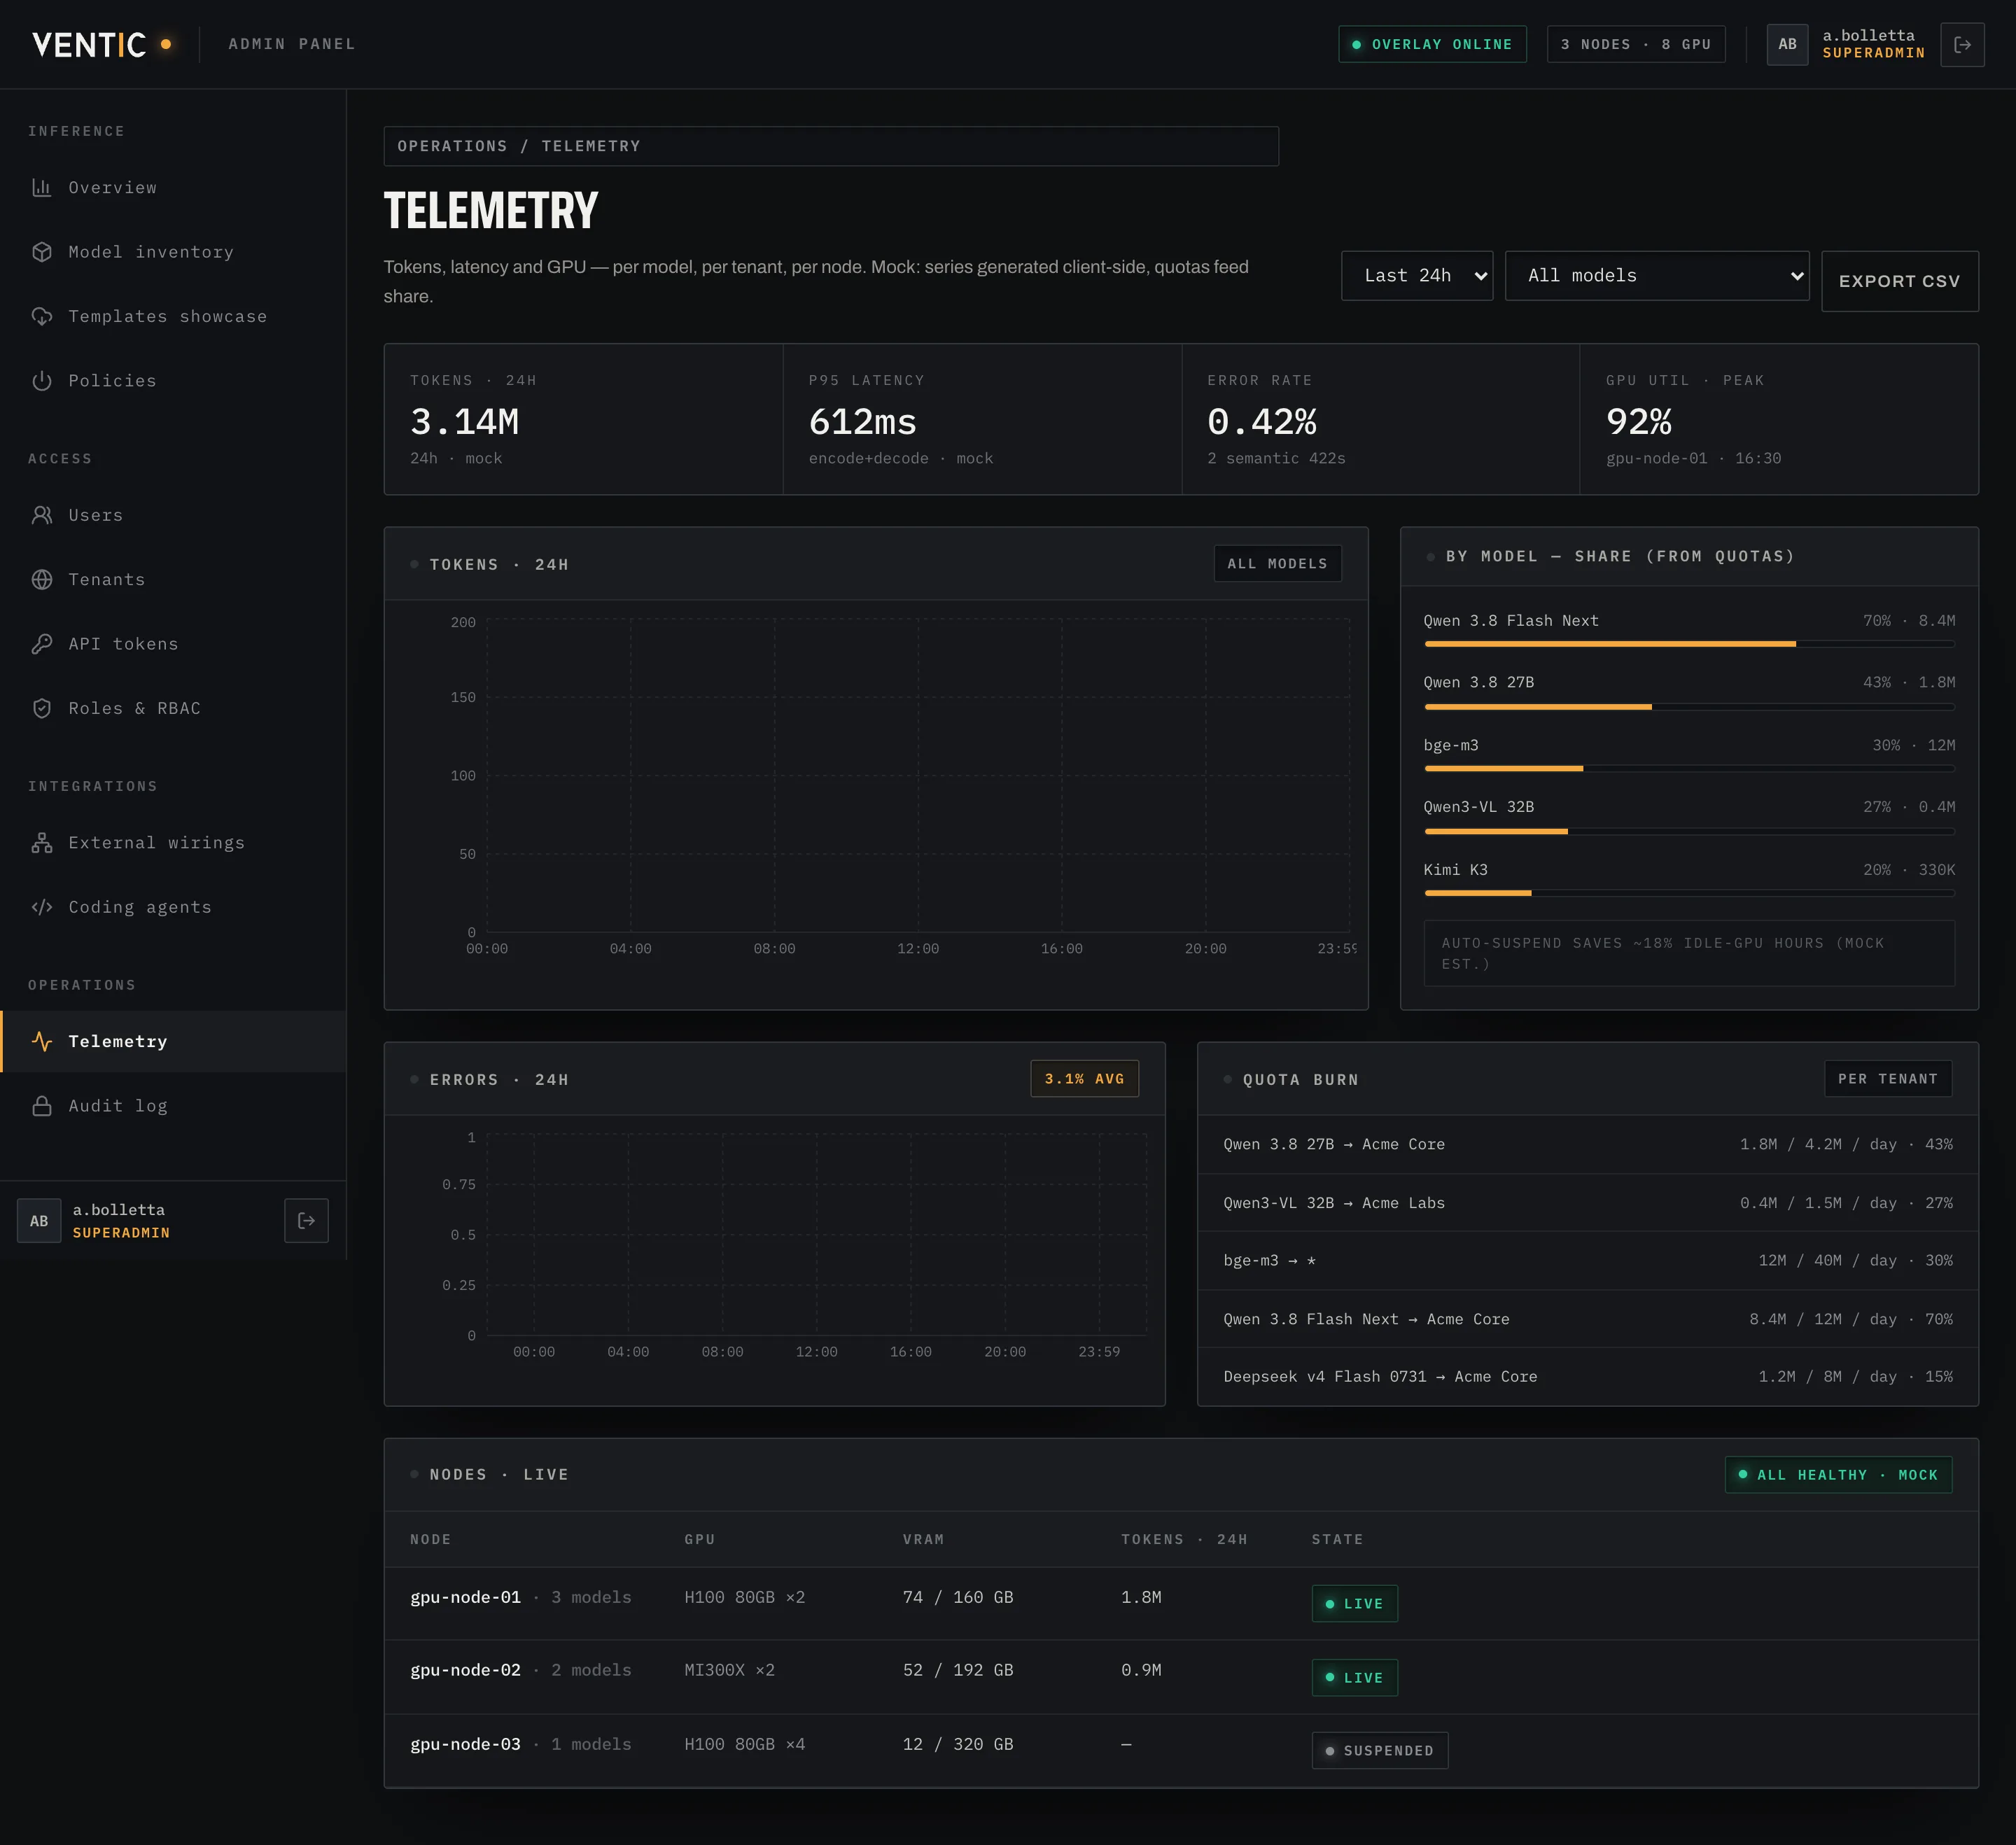
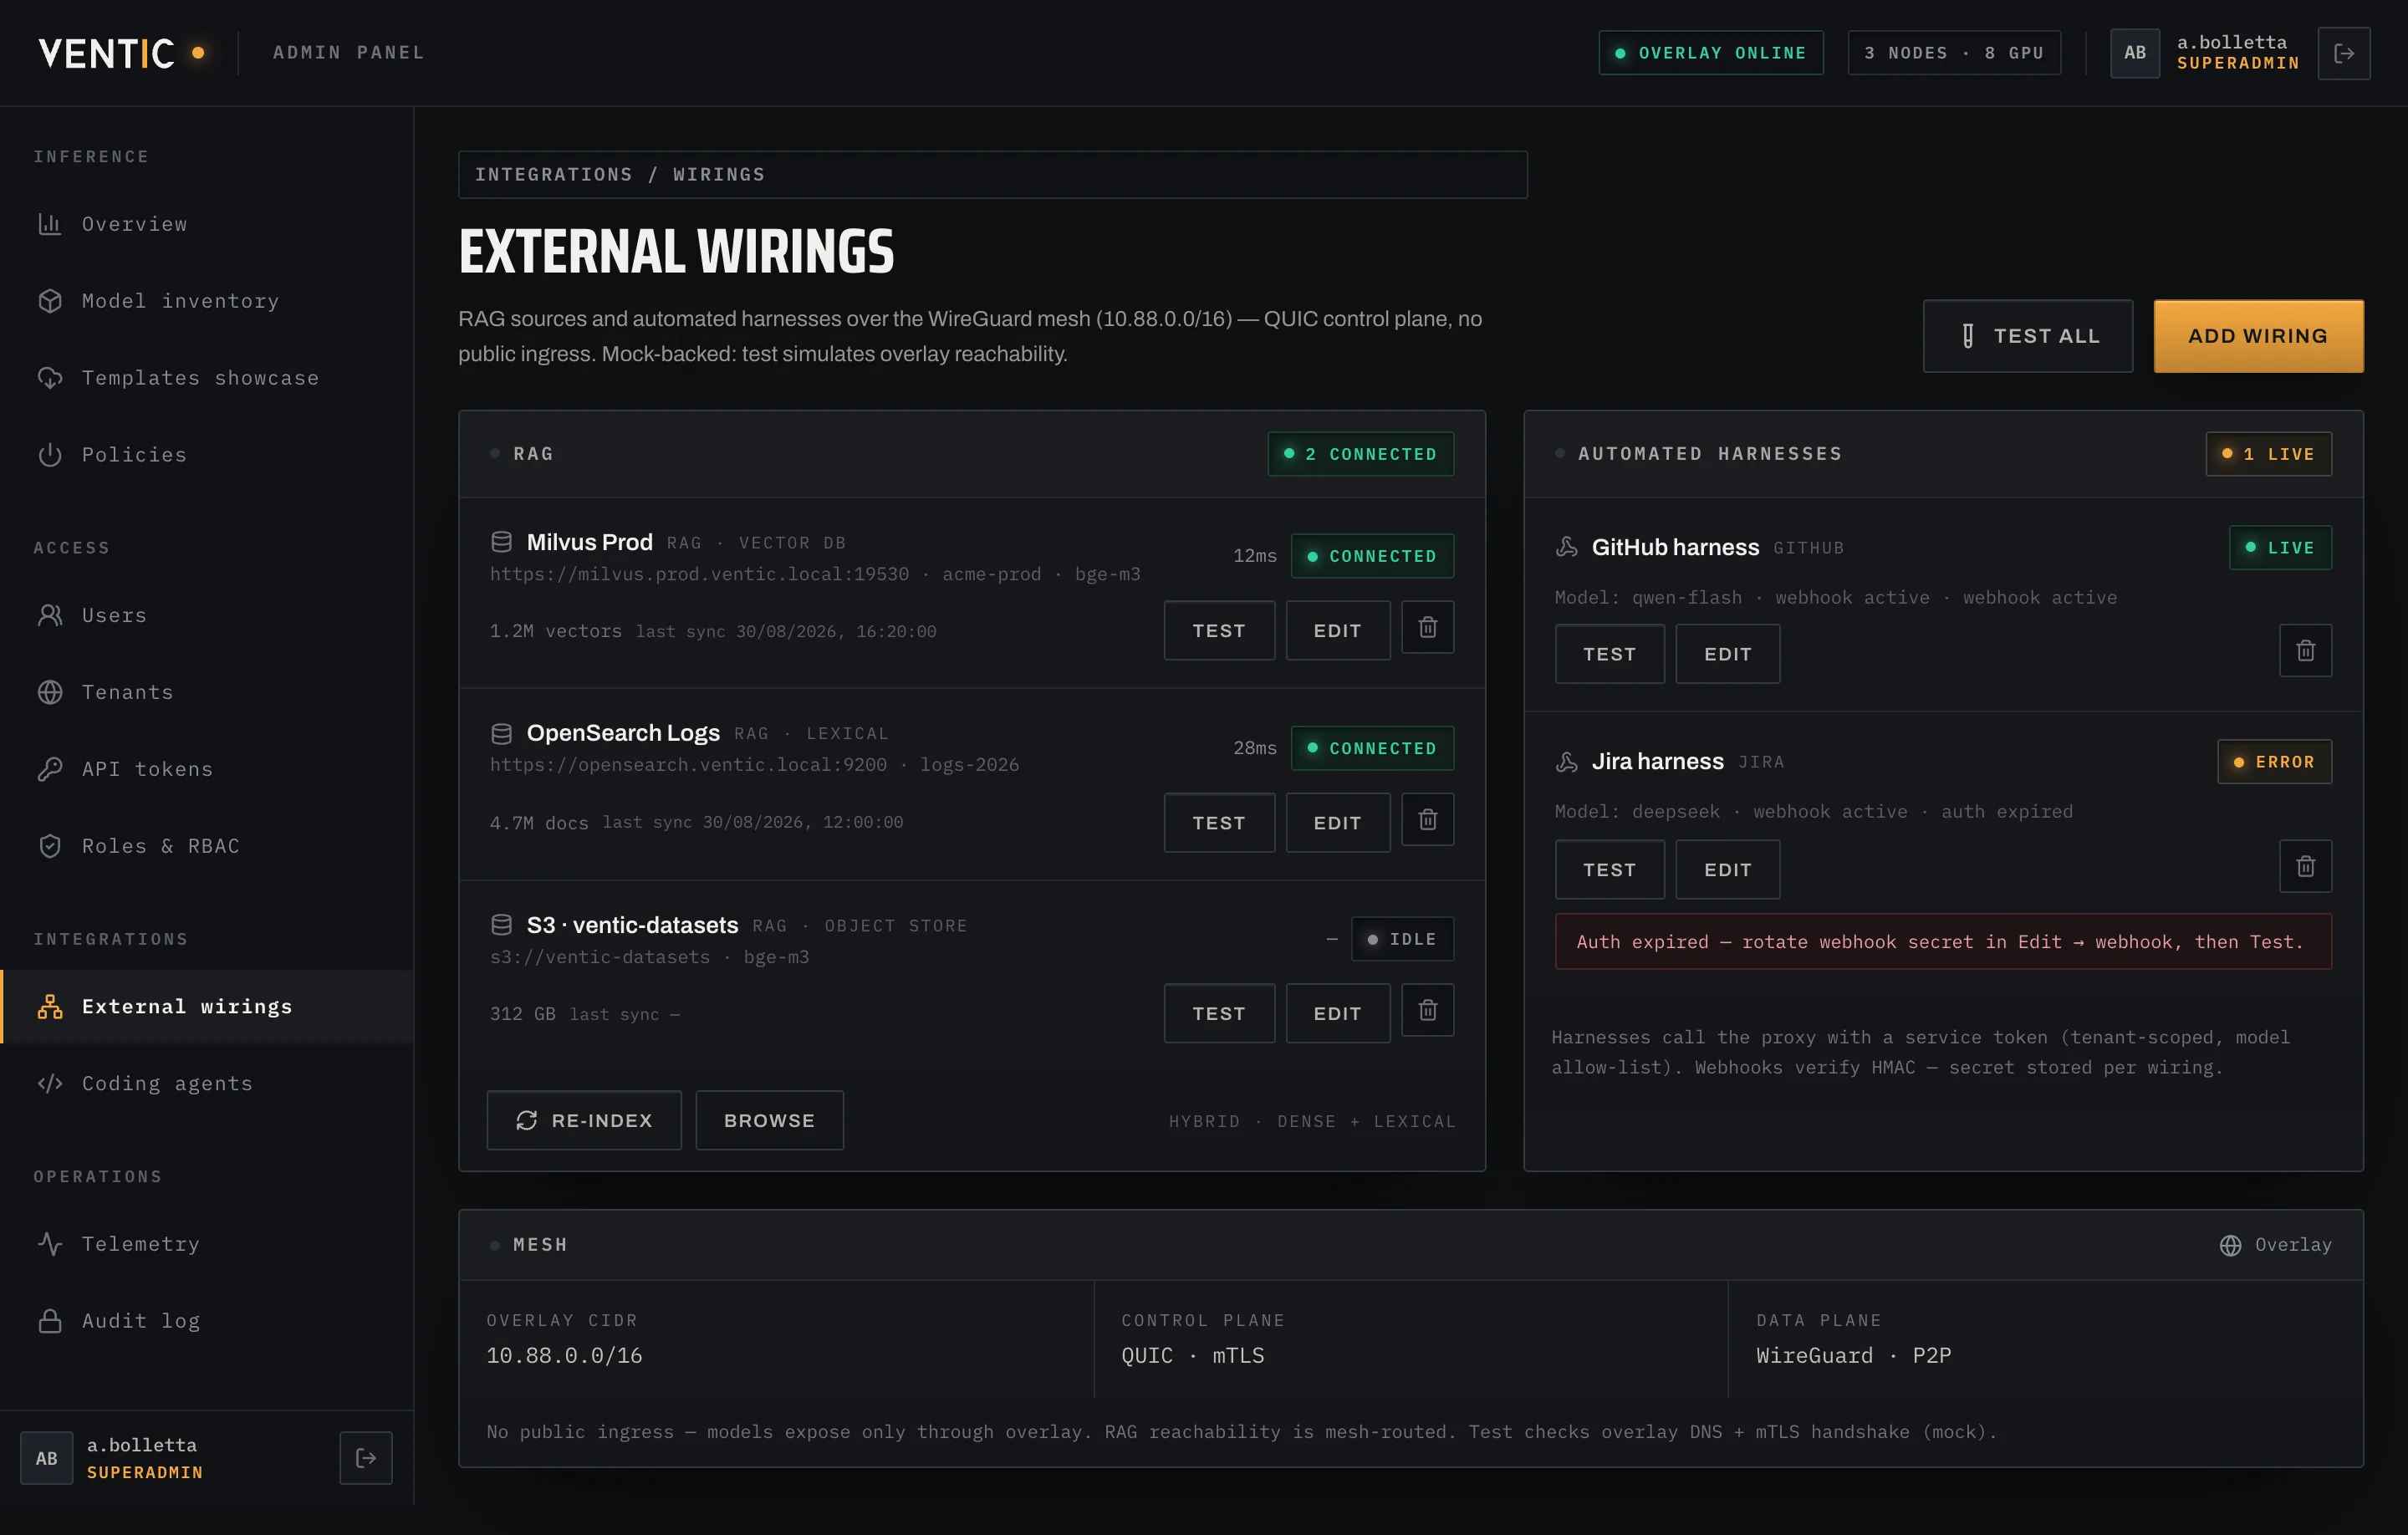
Users and access: users with tenant, role, expiry and token usage, auth provider panel and API token table.Roles and RBAC: endpoint permission matrix across four roles and rules binding subjects to models.Telemetry: tokens-per-minute chart, GPU/VRAM gauges per node, per-user consumption and recent alerts.External wirings: RAG connectors, platform health, agentic harnesses and coding agent config.
Real panel — sample data
Sound familiar?

I hear you.

01

Token caps and runaway API costs?

Running a medium/large enterprise and looking to move your agentic and/or vibe coding workload to an owned infrastructure with predictable, low costs? Under pressure about getting capped by daily token-window restrictions, or about costs getting out of control due to high API token prices?

02

Open models instead of Sonnet 5, without Chinese endpoints?

Looking to keep a small subscription to proprietary frontier models for hard challenges only, while moving all the rest (95%) of your daily LLM workload to models like DeepSeek 4 (or 4.1) Flash to replace Sonnet 5 — but still having trouble with Chinese API endpoints and business rules, and you don't trust them?

  • Rented GPUs or your own hardware

    Feel free to rely on rented GPU VMs/containers, turning them on and off only when demanded, or run your own private hardware (or both!).

  • Scaling

    Set up your scaling rules effortlessly.

  • Telemetry

    Keep everything under control with a powerful telemetry system.

  • DLP rules

    Block any data leak or security violation with a powerful DLP rule system.

Video · 1:13

Ventic in just
over a minute.

Why LLM providers fall short, how Ventic works and what you get with a private LLM infrastructure.

Why Ventic

LLM providers
are inadequate.

Provider LLMs are perfect for very specific, personal tasks. Inadequate for agentic and business work.

Subscription3 limiti
01 — SUBSCRIPTION

Narrow windows

Quota spent, work stopped. For a person it’s a wait; for a night agent it’s a failure you discover in the morning.

02 — SUBSCRIPTION

Provider outage

When the provider goes down, your product goes with it. No failover helps if the model only lives there.

03 — SUBSCRIPTION

Deprecated models

The same prompts give different results over time. Silent updates, little transparency, no reproducibility.

Per token3 limiti
04 — PER TOKEN

Price per token

On US frontier models the cost per token is high — and grows exactly as your product succeeds.

05 — PER TOKEN

Compliance

Cheap alternatives run on servers outside the EU. If your data must stay in the EU, that’s a dead end.

06 — PER TOKEN

Open-ended budget

LLM usage is unpredictable by nature. Inside a company it becomes a line no one can close at budget time.

Two ways to start

You bring the server,
or we source it.

Either way you get the same: a private OpenAI- and Anthropic-compatible endpoint on a machine you can log into anytime.

BYOH — Bring Your Own Hardware

Use your own servers

You already have GPUs or prefer to buy them. We install the stack: compatibility check, inference engine tuned to your GPU (vLLM / SGLang), Ventic Agent, encrypted overlay, panel and observability.

Ventic Stack license + setup€69.90/ month + VATfor 5 seats included
5 included€69.90
+ €39.99
per extra 10€39.99

E.g. 15 seats → €109.89/mo · 25 seats → €149.88/mo

  • Server and compatibility check — max 1 hour
  • Full inference stack install
  • Ventic Agent for encrypted remote access

Ventic Stack license only for BYOH: €69.90/month + VAT for 5 seats, €39.99 + VAT for each extra block of 10 seats. Volume discounts. Initial setup on request — you can also install yourself.

PaaS

Use our servers

We find the right server at the right price in our catalogue, put it into production and invoice it with the service. All-in — hardware and license included.

All-in, by the hourfrom €1/ hour + VATlicense included
hardware + licensenever per-token
  • Sourced to your criteria: spot or dedicated, EU or US, datacentre or not
  • Bought with an instant SEPA transfer
  • Auto-shutdown when nobody needs it
  • Multicloud for redundancy or failover when critical

You pay only for hours the server is on, license included. Never per token.

How it works

LLMs for Enterprises and Providers
in one stack.

A complete solution to deliver LLMs to people and agents in a controlled way. Like an enterprise Kubernetes for LLMs: declare intent via GUI or CLI manifests, Ventic reconciles desired state — without touching drivers, kernels or inference engine flags.

  1. 01

    Server sourcing

    The right machine sourced at the right price on your criteria. Purchased with an instant SEPA transfer.

    PaaS only
  2. 02

    Provisioned ready

    Your server configured in minutes. Or provisioned from catalogue, sized for the models and workload characteristics you need — LLM and embedding together on a tuned inference engine (vLLM, SGLang).

    in minutes
  3. 03

    Zero-exposure reach

    Private encrypted overlay that self-configures and traverses NAT. No public IP, no hand-rolled VPN, no ports open to the world.

    zero exposure
  4. 04

    Lifecycle management

    Fair scheduling, auto-recovery after spot reclaim, shutdown in quiet hours, metrics and alerts. With support included.

    continuous

Request lifecycle

Your app talks to the proxy as if it were OpenAI. The proxy forwards over the encrypted overlay to Ventic Agent on the GPU node. The answer comes back the same way — no public hop.

01
Your app

OpenAI / Anthropic SDK unchanged. Only the endpoint URL changes.

02
LLM proxy

Single endpoint. Authenticates, enforces RBAC and quotas, then forwards.

03
Encrypted overlay

mTLS channel that traverses NAT. Nodes expose no ports.

04
Ventic Agent

Receives, queues fairly, feeds the inference engine.

05
Inference engine

Inference tuned for that model on that GPU (vLLM / SGLang). Replies to the proxy, proxy to you.

No public IP. No manual VPN. The relay may be public; your nodes stay closed.
REQUEST PATHControl plane and provisioner stay out of the data path01APPSDK unchanged02LLM PROXYauth · RBAC · quotas03mTLS OVERLAYNAT traversal04VENTIC AGENTfair queue05ENGINEvLLM · SGLangresponse — same path back

Declare intent. Ventic reconciles.

Like Kubernetes: describe the endpoint in a manifest, apply it from the CLI and get ready-to-use credentials — then actually use them, e.g. inside opencode.

llm-team.yaml
yaml
apiVersion: ventic.io/v1kind: LLMEndpointmetadata:  name: team-coding  tenant: acmespec:  model: qwen3.8-27b  engine: vllm  # TP=2, ottimizzato per la GPU  replicas: 2  region: eu-south  network:    overlay: mTLS    publicIP: none  auth:    rbac: [dev, agent]    quota: 2M tokens/day  scale:    toZero: 15m  # spegne quando nessuno lo usa    maxReplicas: 4
manifest · intent-based, like Kubernetes
terminal
dev@acme:~/acme$ventic apply -f llm-team.yaml

manifest valid — kind: LLMEndpoint / team-coding (tenant: acme)

→ intent sent to control plane…

✓ node gpu-node-03 attached via mTLS overlay · eu-south · no public IP

✓ weights qwen3.8-27b loaded · vLLM engine (TP=2) started

✓ endpoint READY in 3m 12s · replicas 2/2 · scale-to-zero 15m

credentials issued — tenant acme

export OPENAI_BASE_URL="https://llm.ventic.local/v1"export OPENAI_API_KEY="sk-vent-7f3a…9c2e"export ANTHROPIC_BASE_URL="https://llm.ventic.local/anthropic"export ANTHROPIC_AUTH_TOKEN="sk-vent-7f3a…9c2e"
dev@acme:~/acme$opencode run "add backoff retry to syncBilling() and cover it with tests"

◆ opencode · model ventic/qwen3.8-27b via private proxy

◇ read src/billing.ts (212 lines) + 2 related files — context stays on overlay

◇ patch src/billing.ts + tests/billing.test.ts

✓ tests: 14 passed · diff ready to commit

✓ done via private LLM — 0 tokens billed by the public provider

dev@acme:~/acme$
Recorded demo — sample keys and endpoints
Platform

A stack you own,
not a service you ship data to.

Panel, proxy and observability run on your Docker infra — data stays with you. Only our agent runs on the GPU nodes. Between them, an encrypted overlay that self-configures and traverses NAT with no public IPs or VPN to maintain. An enterprise Kubernetes for LLMs: intent-based, manage everything from GUI or via CLI with manifest files — declare desired state, Ventic reconciles it.

Always includedOptional — enable only if needed
How components interact and where they runClosed nodes · no public IP · mTLS
WORKSTATIONSSDK unchanged — only the URL movesYOUR DOCKER INFRASTRUCTUREon-prem or cloud — data stays hereOVERLAYencrypted mTLSINFERENCE NODESyour GPUs or from the catalogueVENTIC CONTROL PLANEremote — run by us, always presentOpenAI / Anthropic APImTLS overlaypowers on / off — your machines onlyintent · manifestattaches the node to your overlayacquiresCODING AGENTSClaude Code · Copilot · CursorAPPS & SERVICESbackends · jobs · automationsOPENAI / ANTHROPICexisting SDKs and toolsLLM PROXYsingle endpoint · auth · RBAC · quotasADMIN PANELusers · models · policyOBSERVABILITY LGTMlogs · metrics · tracesON-PREM INPsees and drives your machines onlyoptionalOPENRAG · QDRANT · HARNESSESmodules enabled on requestRELAYmTLS · NATINP PAAStakes the intent, sources the nodesbursts beyond your machines, even on-premalways onBILLING & RESALEper-tenant usage · resalesubscription or per-tokencoming soonCLOUD GPU CATALOGUEspot or dedicated · EU / USinstant SEPA purchasegpu-node-012×H100 80GBgpu-node-022×MI300Xgpu-node-03autostarted on demandLit slots = model replicas currently running on that node.no public IPno VPN to maintain
Data path — request and responseEncrypted mTLS overlayControl path — provisioningOptional or coming soon
Autoscaling & scale-to-zero
  • Above 80% load: adds a replica.
  • Below 25% for 10 minutes: removes one.
  • No requests for 15 minutes: powers the node off. Wakes on next call.
Inference Node Provisioner (INP)
INP on-prem (optional)your machines only

Runs in your infra. Sees and manages only customer machines: powers them on/off per manifests. If absent, scaling is delegated to Ventic's Provisioner.

INP PaaS — Ventic side (always present)always on

Runs on Ventic control plane. Acquires cloud GPUs (spot/dedicated, EU/US) and attaches them via overlay to your stack — even when you start on-prem and need to burst beyond your machines.

Billing & Resalecoming soon

Will meter per-tenant usage for resale as subscription or per-token. Architecture ready — feature coming soon.

Ventic INP PaaS always exists and can supply even on-prem stacks — on-prem INP is optional and sees only your machines. Billing coming soon for subscription/token resale.

Lifecycle

Scales with load. Shuts down when idle.

> 80% load

Adds a GPU replica to absorb the spike.

< 25% for 10 min

Removes a replica. You pay only for what you use.

0 requests for 15 min

Powers the node off. Wakes on the next call.

Spot reclaimed

Agent reschedules to another provider with no hands on keyboard.

INFERENCE NODE PROVISIONERwatches load, decides and acts — on-prem or Ventic side> 80% load< 25% for 10 min0 requests for 15 minfirst call → wakes upreschedules on another providerRUNNINGn replicas liveSCALE OUT+1 GPU replicaSCALE IN−1 replicaPOWERED OFFscale-to-zero · zero costSPOT RECLAIMEDautomatic re-provisioning

All automatic. No night ops.

01

Your workstations

On the desktops doing the work
Coding Agent wiring tool

Configures the coding agent your team already uses. No hand procedure, no endpoint to paste.

02

Your Docker infrastructure

Wherever you decide — on-prem or cloud
Admin panel

Users, roles, models, quotas and policy. The panel shown below.

LLM proxy

One endpoint, OpenAI- and Anthropic-compatible. Existing clients stay as they are.

LGTM stack

Logs, metrics and traces with Grafana in front. Usage data never leaves you.

Inference Node Provisioner (on-prem)Optional — enable only if needed

Optional. Runs in your infra and sees only your machines: powers them on/off per manifests. If absent, scaling is delegated to Ventic's Provisioner.

OpenRAGOptional — enable only if needed

Retrieval pipelines over your own documents.

QdrantOptional — enable only if needed

Vector database backing the RAG collections.

Embedding modelOptional — enable only if needed

Indexing served by the same inference stack.

Deepseek harnessOptional — enable only if needed

Agentic harness, ready to wire to a model.

OpenclawOptional — enable only if needed

Alternative agentic harness, same wiring.

LangChain adapterOptional — enable only if needed

Native LangChain integration: your chains and tools call Ventic as OpenAI, with full OpenTelemetry tracing.

n8n nodeOptional — enable only if needed

n8n workflow node for Ventic: internal no-code automations that stay inside your network, no data to external providers.

Agentic observabilityOptional — enable only if needed

Every agent call traced in Grafana/LGTM: latency, tokens, errors and alerts on the channel you choose.

03

Encrypted overlay network

Relays public, nodes closed
Relay node

Routes traffic to hosts that expose nothing to the internet. Relay may be public; your nodes stay closed behind NAT.

04

The inference nodes

On the GPUs — yours or from the catalogue
Ventic host agent

Keeps the LLM up, exposes it over the overlay and shares it fairly. The only piece on the node.

Inference engine

Based on vLLM and SGLang, tuned for that model on that GPU, serving LLM and embedding together.

05

Ventic Control Plane (remote)

Managed by us — always present
Inference Node Provisioner (PaaS)

Always on, Ventic side. Receives intent from your stack, acquires cloud GPUs (spot/dedicated, EU/US) and attaches them via overlay — even when you start on-prem and need to burst beyond your machines.

Billing & Resale — coming soonOptional — enable only if needed

Meters per-tenant usage and prepares resale as subscription or per-token. Architecture ready — feature coming soon.

Optional parts are switched on only if you need them: the minimum stack is agent, overlay and proxy. Ventic PaaS INP is always present and can supply even on-prem stacks; on-prem INP is optional and sees only your machines.

What you get

Everything you need,
so you stop thinking about it.

Book a technical call

Always up

If the spot is reclaimed, Ventic reschedules and restores on its own — on another provider if needed.

Multi-user, fair

One machine shared fairly: predictable context windows and exactly scheduled workload.

No public IP

Encrypted overlay traverses NAT to reach the server even if it’s not exposed. Self-configuring: no fragile config.

Observability

GPU, CPU and OS in view, per-user token usage live, alerts on any channel you choose.

Accounts and API keys

Panel to create, rotate and revoke users and keys. 2FA and external auth providers.

Scale to zero

If nobody uses the LLM the instance powers off and wakes on the next request. No hours burned idle.

Session policies

See how sessions are used and apply content restrictions per user or key.

Uncensored models

For when commercial filters block the work: hardening, red teaming, bug bounty.

Multicloud

Same model across providers, in redundancy or failover: if one stops, the service doesn’t.

Autonomous agents 24/7

LangChain, n8n and OpenClaw/DeepSeek harnesses: your agents run all night on the private endpoint, with no provider windows or rate limits.

n8n workflows & automation

An n8n node that calls Ventic as if it were OpenAI: internal no-code pipelines with no webhooks to the outside and no data leaving your network.

Agentic observability

OpenTelemetry traces on every agent call — latency, tokens and errors in Grafana/LGTM, with alerts on the channel you choose.

Models

The best open weights,
for coding and agents.

State of the art across three tiers of cost and intelligence. We choose the model with you, based on the job and the GPU in front of you.

ModelTierBest for
Qwen 3.8 27BEfficientHigh volume and assisted coding, at the lowest cost per answer.
Qwen 3.8 Flash NextFastAgents with many steps: where latency matters more than depth.
Deepseek v4 Flash 0731BalancedThe reference trade-off between code quality and throughput.
Kimi K3FrontierThe hardest agentic work, when you need the best open weights.

VRAM, context window and inference engine settings are decided together during server analysis.

Open weights,
your server.

The best open weights are publicly available. Using them via external APIs means sending data to third-party servers — a non-starter for many companies.

With Ventic you download the weights and run them on your machine, where you chose to put it. The model is open; your data stays with you.

EUUSon-prem
Fixed weights, fixed results

The model installed today is the same in six months, byte for byte. No silent updates: evals stay valid, prompts keep behaving the same.

Pricing

Three numbers.
No surprises.

We don’t bill per token. BYOH (Bring Your Own Hardware) pays per-seat license. PaaS pays by the hour, license included. How much the model writes doesn’t change the bill.

Comparison and per-user cost
BYOH · Ventic Stack licenseBYOH only
€69.90/ month + VAT
5 included€69.90
+ €39.99 / 10

E.g. 15 → €109.89 · 25 → €149.88

BYOH only: 5 seats included. Each extra block of 10 seats: €39.99 + VAT. Volume discounts. Setup on request, self-install possible.

PaaS · Ventic 16license included
€1/ h + VAT
hardware+ licensehourly

Qwen 3.8 27B. 16 active users, up to 100 on roster. €160/month business hours, license included.

PaaS · Ventic 64license included
€6/ h + VAT
hardware+ licensehourly

Deepseek v4 Flash 0731. 64 active users, up to 500 on roster. €960/month business hours, license included.

Launch pricing, VAT excluded · license only on BYOH: €69.90/month for 5 seats + €39.99 every 10 extra · business hours = 8 h × 20 days = 160 h/month · PaaS: hardware and license included in hourly rate · Prices indicated are reserved for early access alpha

Get started

Get in touch
to join the alpha.

We help you pick the right setup — BYOH with your servers or PaaS with ours — and start directly from the workload you want to put in production. Alpha stage, invite-only.